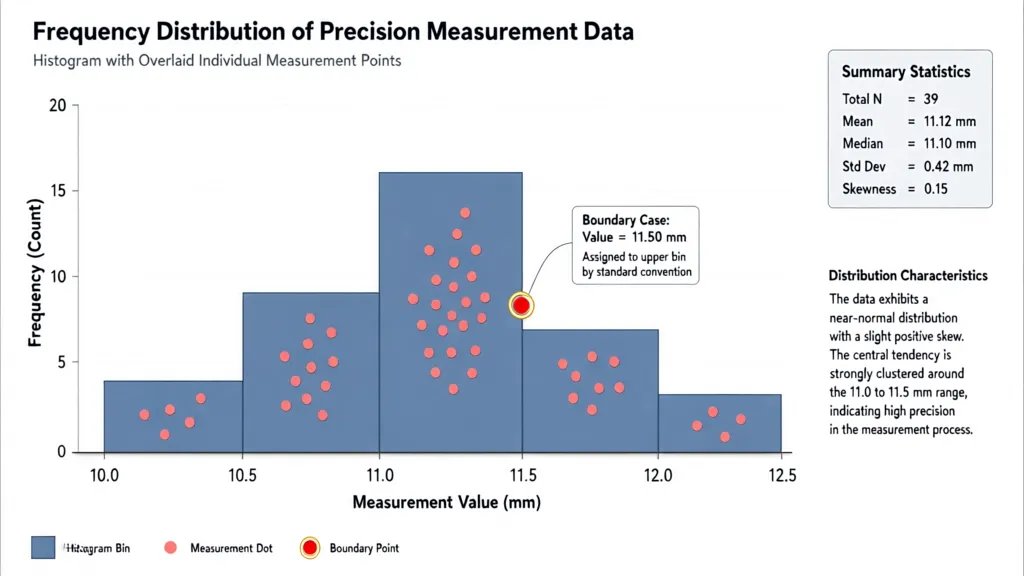
A histogram begins with a range of numbers and divides that range into adjacent intervals called bins. Each bin represents a stretch of the number line; its count tells how many data values fall within that stretch. A bin is not a single value, but a small region in which many different values can be grouped together.
Suppose measurements run from 0 to 10 and the range is divided into five equal bins. The bin width is 2, giving intervals from 0 to 2, 2 to 4, and so on. A value such as 3.6 belongs to the interval from 2 to 4, so it contributes one count to that bin.
edges = [0, 2, 4, 6, 8, 10]
The list contains six edges because five adjoining intervals need six boundary points. Each pair of neighboring edges defines one bin: the first bin lies between edges 0 and 2, the next between 2 and 4. Thinking in terms of edges makes it easier to see both the width of each bin and where the bins begin and end.
Values exactly on a shared edge need a consistent assignment, or they could be counted twice—or not counted at all. NumPy’s histogram convention includes the left edge and excludes the right edge for each bin, except that the final bin also includes its rightmost edge. Thus, with the edges above, a value of 2 belongs to the bin from 2 to 4, while a value of 10 belongs to the last bin.
This convention can be checked with a small example:
import numpy as np

values = [1.9, 2.0, 3.6, 10.0]
edges = [0, 2, 4, 6, 8, 10]

counts, returned_edges = np.histogram(values, bins=edges)

print(counts)
print(returned_edges)
The counts are assigned according to the intervals formed by adjacent edges. Values outside the specified range do not contribute to any bin, so choosing the range determines which observations the histogram can represent.
Visa Physical Gift Card $50 (plus $4.95 Purchase Fee)
(as of November 8, 2026 19:13 GMT +00:00 - More infoProduct prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on [relevant Amazon Site(s), as applicable] at the time of purchase will apply to the purchase of this product.)Counting values with numpy.histogram
The first result, counts, is an array with one entry for each bin. The second result, returned_edges, gives the boundaries used to make those bins. The count at position i belongs to the interval from returned_edges[i] to returned_edges[i + 1].
values = [0.4, 1.2, 1.8, 2.1, 3.7, 4.5]
counts, edges = np.histogram(values, bins=[0, 2, 4, 6])

print(counts)
# [3 2 1]

print(edges)
# [0 2 4 6]
Here, three values fall in the first interval, two in the second, and one in the third. Empty bins are retained too; their count is zero. Keeping those zeros matters because each count remains attached to its position in the sequence of bins.
When bins is an integer rather than an array of edges, NumPy divides the data range into that many equal-width bins. If no range is supplied, the range runs from the smallest value to the largest value in the data.
values = [1, 2, 2, 3, 4, 4, 4, 5]

counts, edges = np.histogram(values, bins=4)

print(counts)
print(edges)
An explicit range can be used with an integer bin count. Values outside that range are ignored, while the requested range is divided into equal intervals:
counts, edges = np.histogram(
    values,
    bins=4,
    range=(0, 8)
)
For ordinary counts, the sum of the bins equals the number of input values that fall within the histogram’s range. This gives a useful check when some observations may lie beyond the chosen edges:
inside_count = counts.sum()
Choosing bin edges and widths
The number of bins determines how much detail the histogram preserves. Wide bins combine many observations and can hide structure; narrow bins reveal finer variation but may leave many bins empty or make random fluctuations look important. The choice is therefore part of the measurement, not merely a display setting.
When the data have a meaningful unit or scale, choose a width that makes sense in that context. For measurements recorded in seconds, a bin width of one second may be easier to interpret than a width of 0.873 seconds. Specify the edges directly when boundaries have practical meaning:
edges = np.arange(0, 11, 1)
counts, edges = np.histogram(values, bins=edges)
np.arange is convenient for evenly spaced edges, but floating-point steps can produce edges that differ slightly from the intended decimal values. For a fixed number of bins between two endpoints, np.linspace states the endpoints and the number of intervals explicitly:
edges = np.linspace(0.0, 10.0, 6)
counts, edges = np.histogram(values, bins=edges)
This creates six edges, and therefore five bins, across the interval from 0 to 10. The third argument to linspace is the number of edge values, not the number of bins.
Equal-width bins are not always the best choice. If observations cover several orders of magnitude, equal spacing may place nearly all the values into the first few bins. Logarithmically spaced edges can give more resolution at the low end while still covering large values:
edges = np.logspace(0, 4, 9)
counts, edges = np.histogram(values, bins=edges)
These edges span powers of ten from 1 to 10,000. Logarithmic edges require positive endpoints; zero and negative values cannot be represented on this scale. Because the bins have different widths, their counts do not have the same interpretation as counts from equal-width bins: a wider interval can collect more values simply because it covers more of the number line.
For unequal-width bins, comparing counts alone can be misleading. A count measures the number of observations in an interval, whereas a density measures count per unit of interval width. With density=True, NumPy scales the result so that the total area of the histogram is one:
counts, edges = np.histogram(values, bins=edges, density=True)
widths = np.diff(edges)

areas = counts * widths
print(areas.sum())
The returned density values are heights, not counts. Multiplying each height by its bin width gives the area of that bin, and those areas sum to approximately one. This distinction becomes important whenever the bin widths are unequal, or when the histogram is intended to represent a probability distribution rather than raw totals.
Reading and using the histogram output
The two arrays returned by np.histogram have different lengths. If there are n bins, counts has n entries and edges has n + 1. The edges describe boundaries; they’re not the horizontal coordinates of the counts.
For a quick check, pair each count with the two edges that define its interval:
for i, count in enumerate(counts):
    left = edges[i]
    right = edges[i + 1]
    print(f"[{left}, {right}): {count}")
The final interval includes its right edge. The printed notation uses a closing parenthesis for every interval, so it is only a shorthand for the usual intervals; the last bin’s right boundary is included by NumPy’s convention.
To draw the result with Matplotlib, stairs accepts the bin values and their edges directly. This preserves the exact boundaries, including bins whose widths differ:
import matplotlib.pyplot as plt

counts, edges = np.histogram(values, bins=edges)

plt.stairs(counts, edges)
plt.xlabel("Value")
plt.ylabel("Count")
plt.show()
A bar chart is another useful representation. Its bar positions are the bin centers, and its widths must be the differences between neighboring edges:
widths = np.diff(edges)
centers = edges[:-1] + widths / 2

plt.bar(centers, counts, width=widths, align="center")
plt.xlabel("Value")
plt.ylabel("Count")
plt.show()
Using one constant bar width when the edges are uneven would draw a different picture from the histogram described by the returned arrays. The vector widths keeps each bar aligned with its own interval.
When the histogram was computed with density=True, use the returned values as bar heights, not as raw counts. For unequal-width bins, the bar areas—not their heights—represent the probability in each interval:
density, edges = np.histogram(values, bins=edges, density=True)

plt.stairs(density, edges)
plt.xlabel("Value")
plt.ylabel("Probability density")
plt.show()
The count in a bin can also be recovered from a density histogram by multiplying the density by the bin width and by the total number of observations included in the histogram:
widths = np.diff(edges)
estimated_counts = density * widths * len(values)
This relationship assumes every value in values lies within the specified edges. If some values are outside the range, use the number included in the histogram rather than the full input length:
inside = (values >= edges[0]) & (values <= edges[-1])
included_count = np.count_nonzero(inside)

estimated_counts = density * np.diff(edges) * included_count