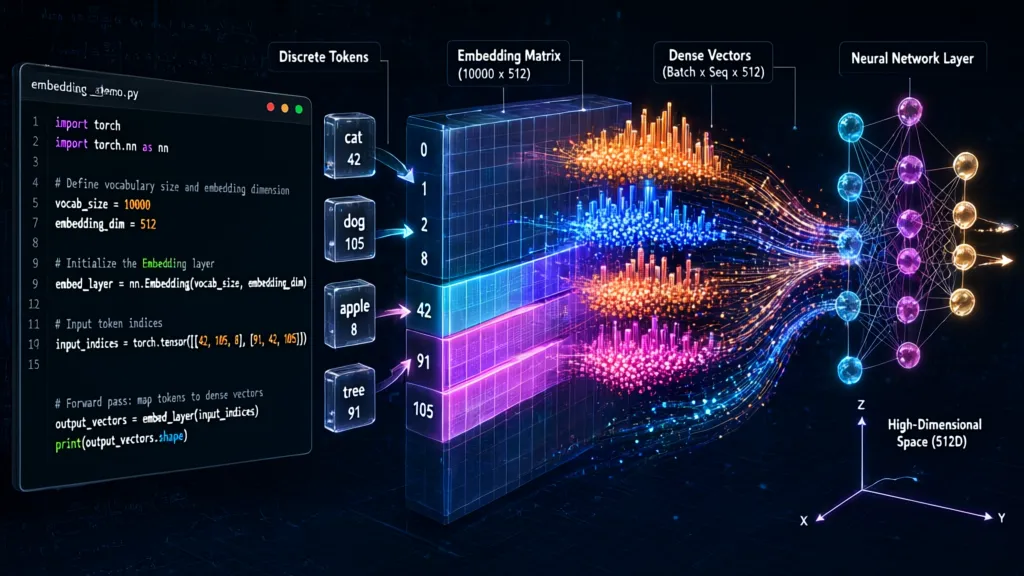
Embedding layers in PyTorch serve as a fundamental building block for many neural network architectures, particularly in natural language processing tasks. They convert categorical variables into dense vectors of fixed size, allowing models to learn relationships between categories effectively. The core idea is to represent discrete inputs, such as words or items, in a continuous vector space where similar inputs have closer representations.
To create an embedding layer in PyTorch, you can use the torch.nn.Embedding class. This class takes two parameters: the number of unique categories (or tokens) and the dimensionality of the embedding vectors. For instance, if you have a vocabulary of 10,000 words and you want each word to be represented by a 300-dimensional vector, you would set it up like this:
import torch
import torch.nn as nn

vocab_size = 10000
embedding_dim = 300

embedding = nn.Embedding(vocab_size, embedding_dim)
Once initialized, you can pass indices of the words to the embedding layer, and it will return the corresponding dense representations. For example, if you want to get the embeddings for the words with indices 1, 2, and 3, you would do:
word_indices = torch.LongTensor([1, 2, 3])
word_embeddings = embedding(word_indices)
Understanding how these embeddings are learned is important. Initially, the embeddings are often initialized randomly, and during training, the backpropagation algorithm adjusts the vectors based on the loss function. This adjustment is what allows the model to capture semantic relationships: words that are used in similar contexts will have their vectors adjusted to be closer together in the embedding space.
One important aspect of embedding layers is that they can be used for various types of data beyond just text. For instance, you might use embeddings for user IDs in recommendation systems or for categorical features in tabular data. This versatility makes them a powerful tool in a data scientist’s toolkit.
However, it’s important to consider the initialization and training of these embeddings. Using pre-trained embeddings, such as Word2Vec or GloVe, can often yield better results, particularly when the training dataset is small. To use pre-trained embeddings in PyTorch, you would typically load the embeddings into your embedding layer as follows:
pretrained_weights = torch.FloatTensor(load_pretrained_embeddings())
embedding = nn.Embedding.from_pretrained(pretrained_weights)
Another consideration when working with embedding layers is the concept of padding. In natural language processing tasks, sentences can vary in length, necessitating padding to ensure uniform input sizes. PyTorch provides tools to handle this, such as the torch.nn.utils.rnn.pad_sequence function, which can assist in batching variable-length sequences. Keeping track of the original lengths is also essential to prevent the model from learning from the padded values.
As you delve deeper into embedding layers, exploring techniques such as dropout regularization becomes crucial. This can help mitigate overfitting, especially in larger models with extensive parameter spaces. Incorporating dropout can be done easily in PyTorch:
class EmbeddingModel(nn.Module):
    def __init__(self, vocab_size, embedding_dim):
        super(EmbeddingModel, self).__init__()
        self.embedding = nn.Embedding(vocab_size, embedding_dim)
        self.dropout = nn.Dropout(0.5)

    def forward(self, x):
        x = self.embedding(x)
        x = self.dropout(x)
        return x
Embedding layers also play a significant role in the idea of transfer learning. By using embeddings trained on large datasets, you can fine-tune your models on specific tasks with relatively little data. This approach allows you to benefit from existing knowledge while adapting it to new challenges. As you experiment with embedding layers, consider the implications of layer freezing during training, which can prevent the embedded weights from being updated.
Embedding layers are a versatile and powerful tool in the machine learning landscape. They provide a means to represent categorical data in a way that neural networks can effectively process. As you implement these layers, keep in mind the various considerations around initialization, padding, and regularization that can impact your model’s performance and scalability.
Now retrieving an image set.
Starbucks Physical Gift Card | $25
$25.00 (as of September 17, 2026 11:49 GMT +00:00 - More infoProduct prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on [relevant Amazon Site(s), as applicable] at the time of purchase will apply to the purchase of this product.)Configuring customizable embeddings for specific tasks
When configuring customizable embeddings for specific tasks, it is essential to tailor the embedding layer to fit the unique characteristics of your dataset. For instance, if you’re dealing with a multi-class classification problem, the embedding layer can be designed to capture the relationships among various classes effectively. You might want to implement a custom embedding initialization strategy based on domain knowledge or specific data distributions.
To create a customizable embedding layer, you can extend the basic nn.Embedding class. This allows you to add additional parameters or methods that can enhance the learning process. For example, you could include a mechanism to adjust the learning rate of the embeddings separately from the rest of the model:
class CustomEmbedding(nn.Module):
    def __init__(self, vocab_size, embedding_dim):
        super(CustomEmbedding, self).__init__()
        self.embedding = nn.Embedding(vocab_size, embedding_dim)
        self.embedding.weight.data.normal_(0, 0.1)  # Custom initialization

    def forward(self, x):
        return self.embedding(x)
Another approach to customizing embeddings is to use a hierarchical structure. This can be particularly useful in scenarios where the data has inherent groupings, such as topics in documents or categories in product data. By structuring your embeddings hierarchically, you can leverage the relationships within these groups to enhance performance:
class HierarchicalEmbedding(nn.Module):
    def __init__(self, vocab_size, embedding_dim, num_groups):
        super(HierarchicalEmbedding, self).__init__()
        self.group_embeddings = nn.ModuleList([nn.Embedding(vocab_size, embedding_dim) for _ in range(num_groups)])

    def forward(self, x, group_indices):
        return self.group_embeddings[group_indices](x)
For tasks that require fine-grained control over the embedding characteristics, consider implementing attention mechanisms. Attention can help the model focus on specific parts of the input, thereby enhancing the quality of the embeddings. That is particularly relevant in natural language processing, where certain words or phrases may carry more significance depending on the context:
class AttentionEmbedding(nn.Module):
    def __init__(self, vocab_size, embedding_dim):
        super(AttentionEmbedding, self).__init__()
        self.embedding = nn.Embedding(vocab_size, embedding_dim)
        self.attention_weights = nn.Parameter(torch.randn(embedding_dim, 1))

    def forward(self, x):
        embedded = self.embedding(x)
        attention_scores = torch.matmul(embedded, self.attention_weights)
        attention_weights = torch.softmax(attention_scores, dim=1)
        return embedded * attention_weights
In addition to custom architectures, you should also consider the training regime for your embeddings. Techniques like gradient clipping can be beneficial, particularly when dealing with large embedding sizes or complex models. This can prevent exploding gradients, which are a common issue when training deep learning models:
optimizer = torch.optim.Adam(model.parameters(), lr=0.001)
torch.nn.utils.clip_grad_norm_(model.parameters(), max_norm=1.0)
Furthermore, to enhance performance, you may want to implement mini-batch training strategies. This allows your model to learn from multiple examples concurrently, improving convergence rates and stability. PyTorch’s DataLoader can be used to efficiently batch your input data:
from torch.utils.data import DataLoader, TensorDataset # Assuminginputsandtargetsare your data tensors dataset = TensorDataset(inputs, targets) data_loader = DataLoader(dataset, batch_size=32, shuffle=True)
As you explore these customization options, remember that the key to effective embeddings lies in understanding the context of your data and the specific needs of your task. Experimenting with different configurations and monitoring their impact on model performance will lead to a deeper understanding of how embeddings can be optimized for various applications. The interplay between embedding design and model architecture can significantly influence the success of your machine learning endeavors.
Optimizing performance and scalability of embedding layers
Optimizing performance and scalability of embedding layers requires a multifaceted approach that considers both the computational resources available and the specific requirements of your neural network architecture. One of the primary strategies for achieving that is through the use of efficient data loading and preprocessing techniques. By ensuring that your data is prepared in a way that minimizes bottlenecks, you can significantly enhance the training speed of your models.
Using PyTorch’s DataLoader is essential for batching your input data effectively. This allows for parallel processing of multiple samples, which can be particularly beneficial when working with large datasets. You can customize the DataLoader to load your embeddings in batches, ensuring that your model trains efficiently:
from torch.utils.data import DataLoader, Dataset

class CustomDataset(Dataset):
    def __init__(self, data, targets):
        self.data = data
        self.targets = targets

    def __len__(self):
        return len(self.data)

    def __getitem__(self, idx):
        return self.data[idx], self.targets[idx]

dataset = CustomDataset(data_tensor, target_tensor)
data_loader = DataLoader(dataset, batch_size=64, shuffle=True)
Another important consideration is the dimensionality of your embeddings. While larger embeddings can capture more nuanced relationships, they also increase the computational load. Experimenting with different embedding sizes can lead to a balance between performance and efficiency. You can implement a simple function to test various embedding dimensions:
def test_embedding_sizes(sizes, vocab_size):
    results = {}
    for size in sizes:
        embedding = nn.Embedding(vocab_size, size)
        # Placeholder for model training and evaluation code
        results[size] = evaluate_model(embedding)
    return results

sizes_to_test = [50, 100, 200, 300]
results = test_embedding_sizes(sizes_to_test, vocab_size)
Additionally, consider using mixed precision training, which can significantly reduce memory usage and speed up computation. PyTorch provides support for this through the torch.cuda.amp module. By enabling mixed precision, you can benefit from faster training times while maintaining model accuracy:
from torch.cuda.amp import autocast, GradScaler

scaler = GradScaler()

for data, target in data_loader:
    with autocast():
        output = model(data)
        loss = loss_function(output, target)

    scaler.scale(loss).backward()
    scaler.step(optimizer)
    scaler.update()
In scenarios where your embedding layer needs to handle a vast number of unique inputs, such as in recommendation systems, you may want to explore techniques like hierarchical softmax or negative sampling. These methods can drastically reduce the computational cost associated with training large embedding layers:
class HierarchicalSoftmax(nn.Module):
    def __init__(self, vocab_size, embedding_dim):
        super(HierarchicalSoftmax, self).__init__()
        self.embedding = nn.Embedding(vocab_size, embedding_dim)
        self.output_layer = nn.Linear(embedding_dim, vocab_size)

    def forward(self, x):
        embedded = self.embedding(x)
        return self.output_layer(embedded)
Moreover, caching frequently accessed embeddings can also improve performance. This can be done by storing the embeddings in memory and using them directly during model inference, which can save time on repeated lookups:
class CachedEmbedding(nn.Module):
    def __init__(self, vocab_size, embedding_dim):
        super(CachedEmbedding, self).__init__()
        self.embedding = nn.Embedding(vocab_size, embedding_dim)
        self.cache = {}

    def forward(self, x):
        if x.item() in self.cache:
            return self.cache[x.item()]
        else:
            embedded = self.embedding(x)
            self.cache[x.item()] = embedded
            return embedded
Lastly, consider using distributed training techniques if your embedding layer is particularly large or your dataset is massive. Using PyTorch’s DistributedDataParallel can help distribute the workload across multiple GPUs, enhancing scalability and reducing training time:
import torch.distributed as dist

dist.init_process_group(backend='nccl')
model = nn.parallel.DistributedDataParallel(model)