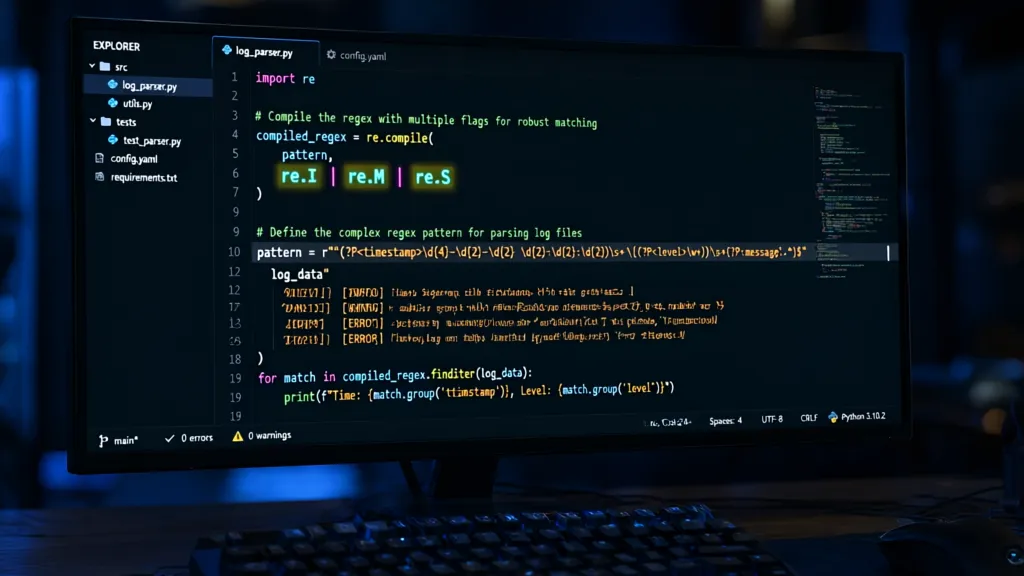
Regular expression flags are a powerful feature in Python’s re module that enable you to modify the behavior of pattern matching. These flags can be passed as optional arguments to various functions, adjusting how the regex engine interprets the patterns you define. A common use case is to enable case-insensitive matching or to allow patterns to match across multiple lines.
Understanding how these flags work is essential for crafting flexible and efficient regex patterns. For instance, using the re.I flag can simplify cases where the case of letters may vary, ensuring that your pattern matches regardless of whether the text is uppercase or lowercase.
import re

pattern = re.compile(r'hello', re.I)
result = pattern.search('Hello there!')
print(result.group())  # Outputs: Hello
Another useful flag is re.M, which allows the ^ and $ anchors to match the start and end of each line within a string, rather than just the start and end of the entire string. That is particularly advantageous in multiline text processing, where you might need to identify line beginnings or endings without having to split the input manually.
text = """Hello
World
Hello again"""

pattern = re.compile(r'^Hello', re.M)
matches = pattern.findall(text)
print(matches)  # Outputs: ['Hello', 'Hello']
There’s also the re.S flag, which enables the dot (.) in your regex to match newline characters, effectively treating the entire string as a single line. This can be particularly useful when you want to capture everything between two delimiters, regardless of line breaks.
text = """Start
middle
end"""

pattern = re.compile(r'Start.*end', re.S)
match = pattern.search(text)
print(match.group())  # Outputs: Startnmiddlenend
These flags can be combined as well, so that you can customize the matching behavior even further. For example, if you want a case-insensitive match across multiple lines, you can combine re.I and re.M like this:
pattern = re.compile(r'hello', re.I | re.M)
result = pattern.findall(text)
print(result)  # Outputs: ['Hello', 'Hello again']
Amazon Physical Gift Card | In a Mini Envelope - Christmas
$25.00 (as of October 19, 2026 14:02 GMT +00:00 - More infoProduct prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on [relevant Amazon Site(s), as applicable] at the time of purchase will apply to the purchase of this product.)Exploring the common flags re.I re.M and re.S
In addition to these common flags, there are more advanced techniques you can employ when working with regular expression flags. For instance, using re.X allows you to add whitespace and comments within your regex patterns, making them easier to read and maintain. This can be particularly useful for complex patterns that might otherwise become unwieldy.
pattern = re.compile(r'''
    ^               # Start of the string
    (?Pw+)   # Capture the name
    s+             # Whitespace
    (?Pd+)  # Capture the value
    $               # End of the string
''', re.X)

text = "example 42"
match = pattern.search(text)
print(match.group('name'))  # Outputs: example
print(match.group('value'))  # Outputs: 42
Another advanced technique is the use of re.A, which makes the regex pattern match only ASCII characters, ignoring any Unicode characters. This can be essential when you are working with data that should strictly conform to ASCII standards.
pattern = re.compile(r'[a-zA-Z]', re.A)
text = "Hello, 世界"
matches = pattern.findall(text)
print(matches)  # Outputs: ['H', 'e', 'l', 'l', 'o']
Moreover, you can also use the re.L flag, which enables locale-dependent matching. This can be particularly useful for applications that need to adapt to different linguistic conventions. However, be cautious with this flag as it could lead to unexpected behavior if the locale settings are not properly configured.
import locale

locale.setlocale(locale.LC_ALL, 'en_US.UTF-8')
pattern = re.compile(r'[a-z]', re.L)
text = "Café"
matches = pattern.findall(text)
print(matches)  # Outputs: ['a', 'e']
These flags not only enhance the functionality of your regex patterns but also allow for more control over how patterns interact with the input data. By mastering these techniques, you significantly increase your ability to manipulate and extract data from text efficiently, regardless of its format or structure. One must remember, however, that with great power comes the need for careful consideration of pattern complexity and performance implications. Testing and profiling your regex patterns can help ensure that your solutions remain performant, especially when dealing with large datasets or complex text structures.
def test_performance(pattern, text):
    import time
    start_time = time.time()
    matches = pattern.findall(text)
    end_time = time.time()
    print(f"Matches: {matches}, Time taken: {end_time - start_time:.6f} seconds")

text = "a" * 10000 + "b" * 10000
pattern = re.compile(r'a+b')
test_performance(pattern, text)
Advanced techniques with regular expression flags
In addition to these common flags, there are more advanced techniques you can employ when working with regular expression flags. For instance, using re.X allows you to add whitespace and comments within your regex patterns, making them easier to read and maintain. This can be particularly useful for complex patterns that might otherwise become unwieldy.
pattern = re.compile(r'''
    ^               # Start of the string
    (?Pw+)   # Capture the name
    s+             # Whitespace
    (?Pd+)  # Capture the value
    $               # End of the string
''', re.X)

text = "example 42"
match = pattern.search(text)
print(match.group('name'))  # Outputs: example
print(match.group('value'))  # Outputs: 42
Another advanced technique is the use of re.A, which makes the regex pattern match only ASCII characters, ignoring any Unicode characters. This can be essential when you’re working with data that should strictly conform to ASCII standards.
pattern = re.compile(r'[a-zA-Z]', re.A)
text = "Hello, 世界"
matches = pattern.findall(text)
print(matches)  # Outputs: ['H', 'e', 'l', 'l', 'o']
Moreover, you can also use the re.L flag, which enables locale-dependent matching. This can be particularly useful for applications that need to adapt to different linguistic conventions. However, be cautious with this flag as it could lead to unexpected behavior if the locale settings are not properly configured.
import locale

locale.setlocale(locale.LC_ALL, 'en_US.UTF-8')
pattern = re.compile(r'[a-z]', re.L)
text = "Café"
matches = pattern.findall(text)
print(matches)  # Outputs: ['a', 'e']
These flags not only enhance the functionality of your regex patterns but also allow for more control over how patterns interact with the input data. By mastering these techniques, you significantly increase your ability to manipulate and extract data from text efficiently, regardless of its format or structure. One must remember, however, that with great power comes the need for careful consideration of pattern complexity and performance implications. Testing and profiling your regex patterns can help ensure that your solutions remain performant, especially when dealing with large datasets or complex text structures.
def test_performance(pattern, text):
    import time
    start_time = time.time()
    matches = pattern.findall(text)
    end_time = time.time()
    print(f"Matches: {matches}, Time taken: {end_time - start_time:.6f} seconds")

text = "a" * 10000 + "b" * 10000
pattern = re.compile(r'a+b')
test_performance(pattern, text)