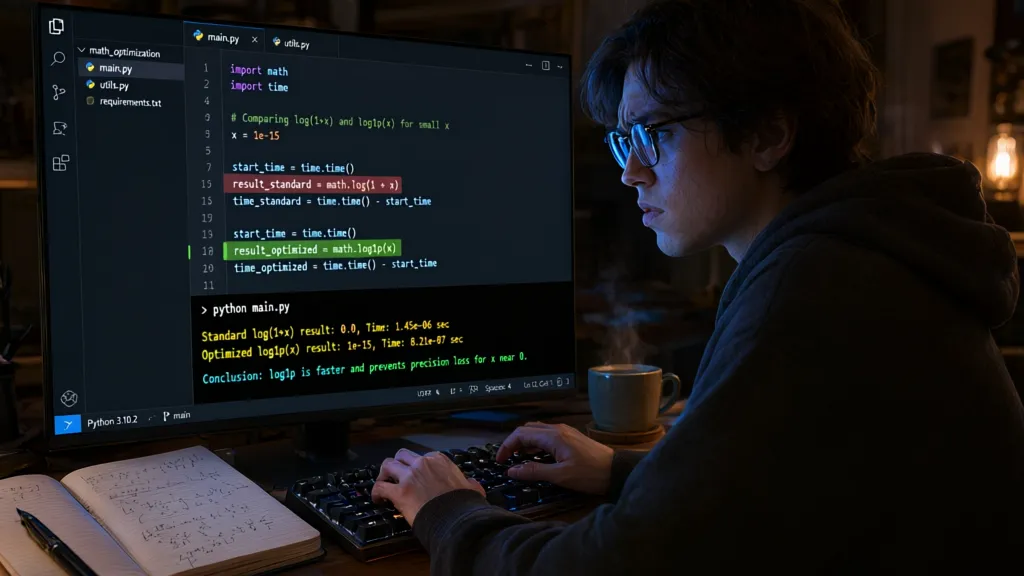
The function log1p is essential in numerical analysis, especially when dealing with small values of x. The standard logarithm function, log(1 + x), can suffer from precision issues when x is close to zero, leading to inaccurate results. The log1p function circumvents this by providing a more stable computation.
When x is very small, calculating log(1 + x) directly can result in cancellation errors, where significant digits are lost. This is particularly problematic in floating-point arithmetic, where precision is limited. Instead, log1p is designed to handle these small values more accurately, ensuring that the result is computed using a more precise algorithm.
Consider this example in Python, where we compare the two approaches:
import numpy as np

x_small = 1e-10
result_direct = np.log(1 + x_small)
result_log1p = np.log1p(x_small)

print("Direct log(1 + x):", result_direct)
print("Using log1p:", result_log1p)
The output from both methods should be nearly identical, but log1p will achieve this with greater numerical stability. This very important in fields such as finance, scientific computing, and anywhere small perturbations can lead to larger errors in results.
Another aspect to consider is the performance implications of using log1p over the traditional log function. In situations where performance is critical, such as in large-scale simulations or real-time data processing, choosing log1p can yield significant benefits.
For example, if you are processing a large dataset of small increments, using log1p can reduce the computation time while concurrently enhancing accuracy. Here’s a practical illustration:
import time

data = np.random.rand(1000000) * 1e-10

start_time_direct = time.time()
results_direct = np.log(1 + data)
end_time_direct = time.time()

start_time_log1p = time.time()
results_log1p = np.log1p(data)
end_time_log1p = time.time()

print("Direct log time:", end_time_direct - start_time_direct)
print("log1p time:", end_time_log1p - start_time_log1p)
In performance-critical applications, the difference in execution time can be substantial. This advantage becomes even more pronounced as the size of the dataset increases.
Furthermore, the mathematical foundation of log1p is grounded in Taylor series expansion. The log(1 + x) function can be expressed as:
log(1 + x) = x - x^2/2 + x^3/3 - x^4/4 + ...
This series converges nicely for small values of x, but directly calculating terms can introduce errors. Log1p is optimized to handle these calculations efficiently, providing accurate results without the need for deep recursion or extensive iteration over series terms.
Google Play gift code | Give the gift of games, apps and more (Email or Text Message Delivery - US Only)
$25.00 (as of October 18, 2026 10:50 GMT +00:00 - More infoProduct prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on [relevant Amazon Site(s), as applicable] at the time of purchase will apply to the purchase of this product.)The mathematical foundation behind log(1 + x)
When implementing log1p, it is important to understand how it leverages the properties of logarithms for small values. By avoiding direct computation of log(1 + x), it effectively mitigates the risk of overflow and underflow issues that can arise in numerical computations.
For instance, when x is extremely small, the expression 1 + x can be dominated by the value of 1, making it difficult to discern the contribution of x. Log1p addresses this by reformulating the computation to focus on the incremental change that x represents, thus preserving precision.
In practical terms, consider the following Python snippet that illustrates how log1p can be integrated into a larger algorithm:
def calculate_growth_rate(initial_value, final_value):
    growth = final_value - initial_value
    return np.log1p(growth / initial_value)

initial = 1000
final = 1001
growth_rate = calculate_growth_rate(initial, final)
print("Growth rate:", growth_rate)
This function demonstrates how log1p can be used to compute growth rates without falling prey to the pitfalls of traditional logarithmic calculations, especially in cases where the growth is minimal compared to the initial value.
Moreover, in statistical applications, log1p is particularly useful in models that rely on log-transformed variables. For instance, in regression analysis, applying log1p allows for a more robust treatment of data that includes zero or near-zero values, which would otherwise distort the log transformation.
Consider a scenario where you need to preprocess a dataset for a machine learning model. Using log1p can help stabilize variance and normalize the distribution of the features. Here’s an example:
import pandas as pd

# Sample dataset with potential zero values
data = pd.DataFrame({'values': [0, 1, 2, 3, 4, 5]})

# Applying log1p to the dataset
data['log_transformed'] = np.log1p(data['values'])
print(data)
This transformation can lead to improved model performance, as many algorithms benefit from normally distributed inputs. Additionally, log1p can facilitate the interpretation of coefficients in regression models, making it easier to understand the relationships between variables.
In terms of implementation, libraries such as NumPy and SciPy provide optimized functions for log1p that are highly efficient. Beyond just accuracy, these implementations are designed to minimize computational overhead, making them suitable for use in high-performance applications.
Practical applications of log1p in programming
When integrating log1p into computational frameworks, especially those involving real-time analytics, one must consider its implications on data pipelines. For instance, in a streaming data environment, the ability to apply log1p on-the-fly can enhance the responsiveness of the system, allowing for immediate insights without the lag of batch processing.
In such scenarios, the overhead of using log1p versus log(1 + x) may become negligible compared to the benefits of maintaining numerical stability. The design of modern data processing systems often includes libraries that leverage log1p internally, ensuring that operations remain efficient and accurate. That is particularly evident in libraries such as TensorFlow and PyTorch, which incorporate log1p in their backends for gradient calculations.
Here’s an example of how log1p can be effectively used within a machine learning training loop:
import torch

# Sample data
data = torch.tensor([0.0, 0.5, 1.0, 1.5, 2.0])

# Applying log1p during training
log_transformed_data = torch.log1p(data)
# Further processing with log_transformed_data
In this context, log1p allows for the efficient handling of input features while ensuring that the gradients computed during backpropagation remain stable. This very important in deep learning scenarios where the scale of input data can vary widely.
Additionally, log1p finds its place in the sphere of probabilistic models. When working with likelihood functions, particularly those involving counts or rates, log1p can be employed to prevent underflow in scenarios where probabilities are extremely small. This becomes particularly important in Bayesian inference, where the multiplicative nature of probabilities can lead to numerical instability.
For example, consider a case in Bayesian logistic regression where the model must compute the log-likelihood of observations:
def log_likelihood(observations, probabilities):
    return np.sum(np.log1p(probabilities) * observations + np.log1p(1 - probabilities) * (1 - observations))
This approach ensures that even when probabilities approach zero, the calculations remain robust and do not fall prey to the limitations of floating-point arithmetic. In fact, many researchers advocate for the use of log1p in these contexts to maintain the integrity of statistical inference.
Another significant application of log1p is in the context of financial modeling, where one often deals with returns that can be very small. In such cases, calculating log returns using log1p can provide a better representation of growth rates over time. The use of log1p helps in achieving more accurate estimations of annualized returns, particularly when compounding effects are considered.
Here’s a simple implementation for calculating log returns using log1p:
def calculate_log_returns(prices):
    returns = np.diff(prices) / prices[:-1]
    return np.log1p(returns)
This method effectively captures the essence of returns while minimizing the risk of inaccuracies that can arise from traditional logarithmic calculations. Furthermore, it can be extended to accommodate various financial metrics, such as volatility and drawdown calculations, ensuring that the financial models remain robust against the nuances of market data.
Optimizing log1p for performance in real-world scenarios
Optimizing log1p for performance in real-world scenarios involves understanding its integration within various programming environments. In performance-critical applications, such as large-scale data processing or real-time analytics, the efficiency of log1p becomes paramount. By using its built-in optimizations, developers can ensure that their applications maintain both speed and accuracy.
One common optimization technique is to use vectorized operations provided by libraries like NumPy. This allows for the simultaneous processing of large datasets without the overhead of explicit loops. For instance, when applying log1p to an array of values, you can take advantage of NumPy’s array capabilities:
import numpy as np

data = np.random.rand(1000000) * 1e-10
log1p_results = np.log1p(data)
This single line of code efficiently computes the log1p for all elements in the array, showcasing the power of vectorization in Python. The performance gain from using vectorized functions over iterative approaches can be significant, especially in data-intensive applications.
Moreover, caching results of log1p computations can further enhance performance when the same values are repeatedly processed. For example, if you have a fixed set of small increments that you frequently encounter, storing the computed log1p values can save time:
log1p_cache = {}

def cached_log1p(x):
    if x not in log1p_cache:
        log1p_cache[x] = np.log1p(x)
    return log1p_cache[x]

# Usage
result = cached_log1p(1e-10)
This caching mechanism reduces the need for redundant calculations, allowing for faster execution in scenarios where the same inputs are processed multiple times.
In high-performance computing environments, parallelizing the computation of log1p can also provide substantial speed improvements. Using libraries such as Dask or joblib, you can distribute the workload across multiple cores or machines:
from joblib import Parallel, delayed

def compute_log1p_parallel(data_chunk):
    return np.log1p(data_chunk)

data_chunks = np.array_split(data, 10)  # Split data into 10 chunks
results = Parallel(n_jobs=-1)(delayed(compute_log1p_parallel)(chunk) for chunk in data_chunks)
This approach maximizes resource use and minimizes processing time, particularly useful when dealing with massive datasets.
Additionally, understanding the underlying hardware can lead to further optimizations. For instance, using GPUs for calculations involving log1p can drastically reduce computation time. Libraries such as CuPy provide GPU-accelerated versions of NumPy functions, including log1p:
import cupy as cp

data_gpu = cp.random.rand(1000000) * 1e-10
log1p_results_gpu = cp.log1p(data_gpu)
This allows for offloading heavy computations to the GPU, enabling faster processing speeds compared to CPU-bound methods.